The short version
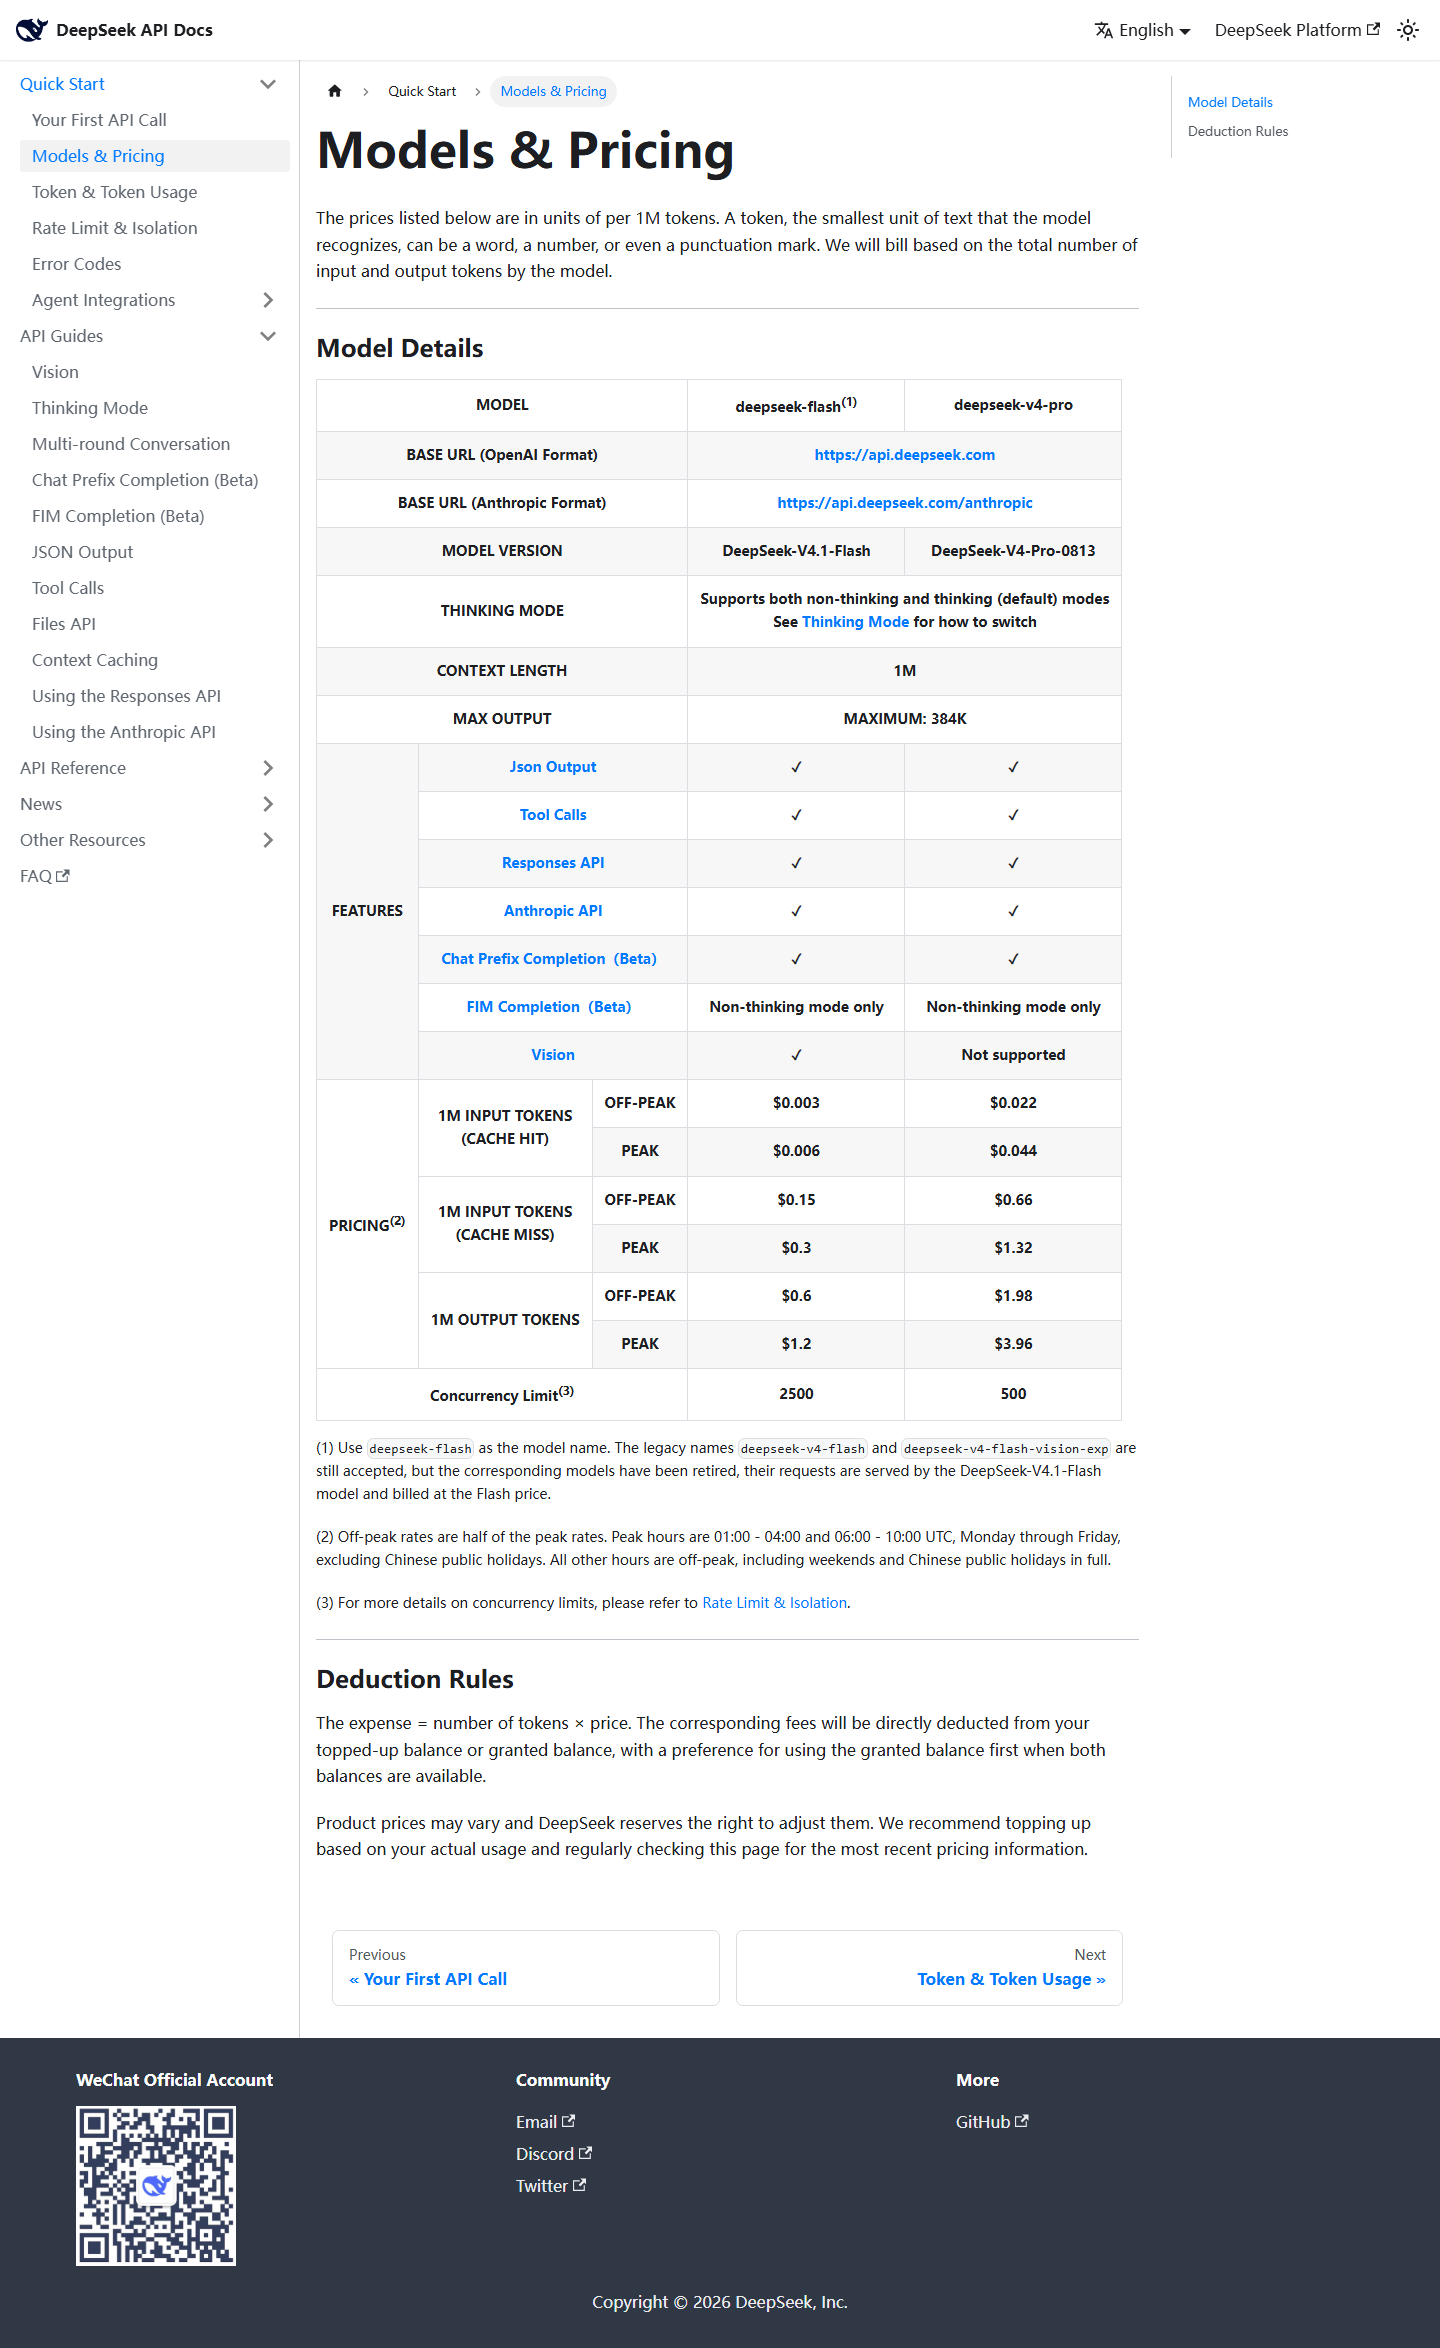
Checked against the official DeepSeek API docs pricing page on 2026-09-21 (proxied browser session; every number below was transcribed from the rendered page’s text layer, screenshot attached). Prices are USD per 1M tokens:
| Per 1M tokens (USD) | deepseek-flash — off-peak | deepseek-flash — peak | v4-pro — off-peak | v4-pro — peak |
|---|---|---|---|---|
| Input, cache hit | $0.003 | $0.006 | $0.022 | $0.044 |
| Input, cache miss | $0.15 | $0.30 | $0.66 | $1.32 |
| Output | $0.60 | $1.20 | $1.98 | $3.96 |
Table mechanics, from the same page: model version DeepSeek-V4.1-Flash vs DeepSeek-V4-Pro-0813;
1M context length and 384K maximum output shown in the Model Details block; JSON output, tool
calls, Responses API and Anthropic-format API on both models; vision on flash, “Not supported”
on v4-pro; concurrency limit 2500 (flash) vs 500 (pro). Base URLs: api.deepseek.com
(OpenAI format) and /anthropic (Anthropic format).
Three arithmetic facts we re-computed from the page, not copied from it
1. Cache-hit input is exactly 50× cheaper than cache-miss on flash — and only 30× on pro. $0.15 ÷ $0.003 = 50; $0.66 ÷ $0.022 = 30 (both states, verified across all four cache cells). A 2% -price cached read is aggressive against the cache-discount conventions of western APIs, and the flash/pro split means the “cache discount” is a per-model policy, not a platform constant. For long-lived agent sessions that re-send a big system prompt, the flash tier’s cached leg ($0.003-0.006) makes prompt-heavy workloads a rounding error — as long as prefix caching actually hits, which is a request-shape property, not a pricing one.
2. Peak is exactly 2× off-peak in all twelve price cells. We multiplied every off-peak number by two against its peak sibling; all twelve match with zero drift. The discount is structural (“Off-peak rates are half of the peak rates” — page footnote), not decorative. Peak hours are printed in the footnote as 01:00-04:00 and 06:00-10:00 UTC, Monday through Friday, excluding Chinese public holidays; everything else — weekends, holidays, other hours — is off-peak. Two practical consequences: the schedule is UTC plus a vendor-country holiday calendar, so a bill-shaping cron has to speak both, not your local time; and all 48 weekend hours are off-peak by default — batch workloads with no latency requirement have a standing 50% discount available to them.
3. Output still costs 4× uncached input on flash. $0.60 ÷ $0.15 = 4, unchanged from pro’s $1.98 ÷ $0.66 = 3… which is not the same ratio: pro output is 3× its input, flash is 4×. Prompt-heavy, answer-short workloads (classification, extraction) get relatively cheaper on pro; generation-heavy ones do not.
The retired-name trap in footnote (1)
The page’s canonical model name is deepseek-flash — no version number. Footnote (1), verbatim
from the capture: legacy names deepseek-v4-flash and deepseek-v4-flash-vision-exp “are still
accepted, but the corresponding models have been retired, their requests are served by the
DeepSeek-V4.1-Flash model and billed at the Flash price.” What that means operationally:
- Old integrations keep working and keep being billed — silently upgraded to a different model generation than the one someone benchmarked when they chose the name.
- Any third-party price list still printing numbers “for deepseek-v4-flash” is, per this page, describing traffic that is actually DeepSeek-V4.1-Flash. When we cross-checked circulating token-price summaries before writing this, several carried figures that match neither column of the table above — stale snapshots of a model that no longer exists under that name.
- There is no versioned alias: if V4.2-Flash replaces V4.1-Flash the same way,
deepseek-flashwill re-point again without a config change. Pin what you benchmarked by testing it, not by trusting the name.
Billing mechanics stated on the page
Fees are “number of tokens × price,” deducted from a topped-up or granted balance, granted
balance consumed first when both exist (relevant if you evaluate with free credits — your paid
balance is untouched until the granted one runs out). The page also reserves the right to adjust
prices “at any time” and recommends re-checking — which is the reason our captures carry a
pricingCheckedDate.
What we did not verify
- We did not run API calls: cache-hit rates, billed totals, and rate-limit behavior are page claims, not measurements. (No account, no keys — this is a terms-level capture.)
- Which upstream architecture V4.1-Flash is, or how the flash tier compares on quality — this page prices models, it does not evaluate them.
- Whether the USD table has hidden regional/currency variants (only the USD table is rendered).
Verdict (terms-level, no score)
No rating — we never spent a token through the API. What the pricing terms do establish: a two-tier menu where the interesting number is not the headline $0.15 but the $0.003 cached leg, an unusually clean 2× peak/off-peak schedule with a UTC print and a vendor-country holiday calendar, and a naming policy that upgrades legacy aliases silently. For cost planning, the page rewards reading footnotes more than headers.
Methodology & sources
- api-docs.deepseek.com/quick_start/pricing/ — captured 2026-09-21 (UTC), proxied real-Chromium
session; full text dump
eval-ops/runs/2026-09-21-group9/deepseek_pricing.txt, screenshotdsf-01-01-official-pricing.png. Ratio arithmetic (50×/30× cache, 2× peak, 4×/3× output) recomputed from the captured cells. - api-docs.deepseek.com quick-start page — same session (
deepseek_home.txt), source for base URLs and thedeepseek-flashcanonical-name footnote. - Third-party price summaries were checked and rejected where they disagreed with the official table; we cite none of them as sources.
- Checked 2026-09-21. DeepSeek’s own page says prices may change at any time; re-verify before quoting.
Related pages
Per-call API pricing is easier to judge against per-seat AI add-ons notion ai pricing — what Notion charges per member for AI, and what it unlocks; figma ai credits — how Figma’s credit packs translate into per-action cost; clickup ai credits — ClickUp’s $9 vs $28 AI tiers and the per-action cost behind them.